SERP API (Bright Data) 每月有 802,752 次造訪,月增率 -5.9%,定價模式為付費、需聯絡報價。Serpex 每月有 2,405 次造訪,成長率 -34.3%,定價模式為免費增值、免費試用、付費。
價格實惠的即時搜尋 API,一次呼叫就回傳結構化 JSON 與網頁正文。
| 面向/指標 | ![]() | |
|---|---|---|
| 官方網域 | brightdata.com | serpex.dev |
| 定價模式 | 付費、需聯絡報價 | 免費增值、免費試用、付費 |
| 每月造訪次數 | 80.28萬 (802,752) | 2405 (2,405) |
| 月流量變化量 | -5.04萬 (-5.9%) | -1255 (-34.3%) |
| 主要市場與市佔 | 🇺🇸 美國 (29.5%) | 🇮🇳 印度 (91.3%) |
| 每月直接造訪 | 38.37萬 | 936 |
| 使用者評分 | 4.6 | 4.3 |
| 支援平台 | 網站 | 網站 |

Bright Data's SERP API is a real-time search engine scraping API that returns Google, Bing, DuckDuckGo, and Yandex results in JSON, HTML, or Markdown, with automatic proxy management, unblocking, and parsing, and geo-targeting at no extra cost.
Pull on-demand search results from Google, Bing, DuckDuckGo, and Yandex, with support for many localized domains and languages.
Receive responses as structured JSON, raw HTML, or Markdown, so pipelines can consume results without custom parsing when you want the fast path.
Proxy rotation, CAPTCHA solving, and unblocking are handled by the API, so you do not have to build or maintain that infrastructure.
Target results from a specific country or language at no extra cost, useful for local SEO and international market research.
價格實惠的即時搜尋 API,一次呼叫就回傳結構化 JSON 與網頁正文。
送出查詢即可取得乾淨、結構化的即時網頁結果 JSON,可直接解析、排序或餵給模型。
用同一組 API Key 把任意 URL 轉成乾淨易讀的 Markdown,去除版型雜訊,讓擷取文本可直接用於 RAG 與摘要。
請求會在數個底層搜尋來源間路由,並搭配健康監控與自動重試,單一來源無結果不會中斷你的管線。
提供 Python、JavaScript、MCP 與 LangChain 的官方函式庫與範例,幾行程式碼就能為代理或應用加入即時搜尋。
免費 / 開源用提示詞取代選擇器,把任何網站變成結構化 JSON
內建代理、瀏覽器與反爬處理的網頁擷取 API
專為 AI 代理、SEO 與資料團隊打造的即時多引擎搜尋結果 API
一次 API 呼叫,從任意網站擷取乾淨的結構化資料

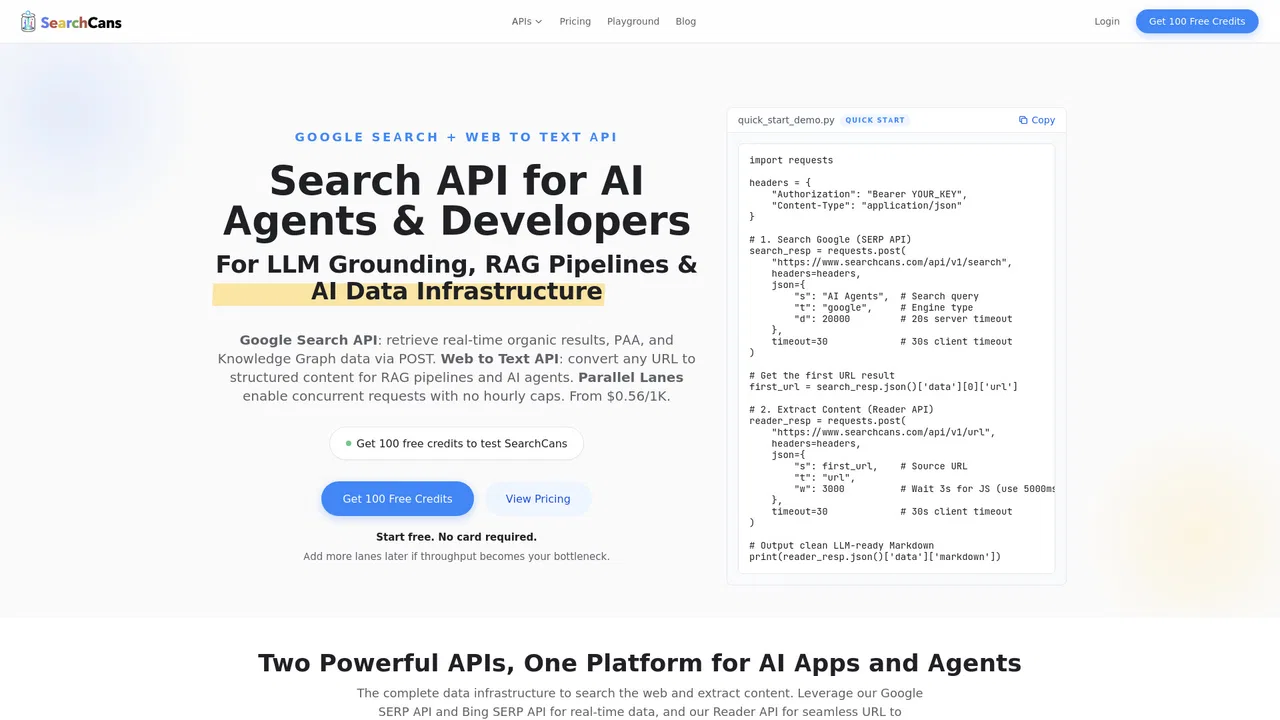
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.