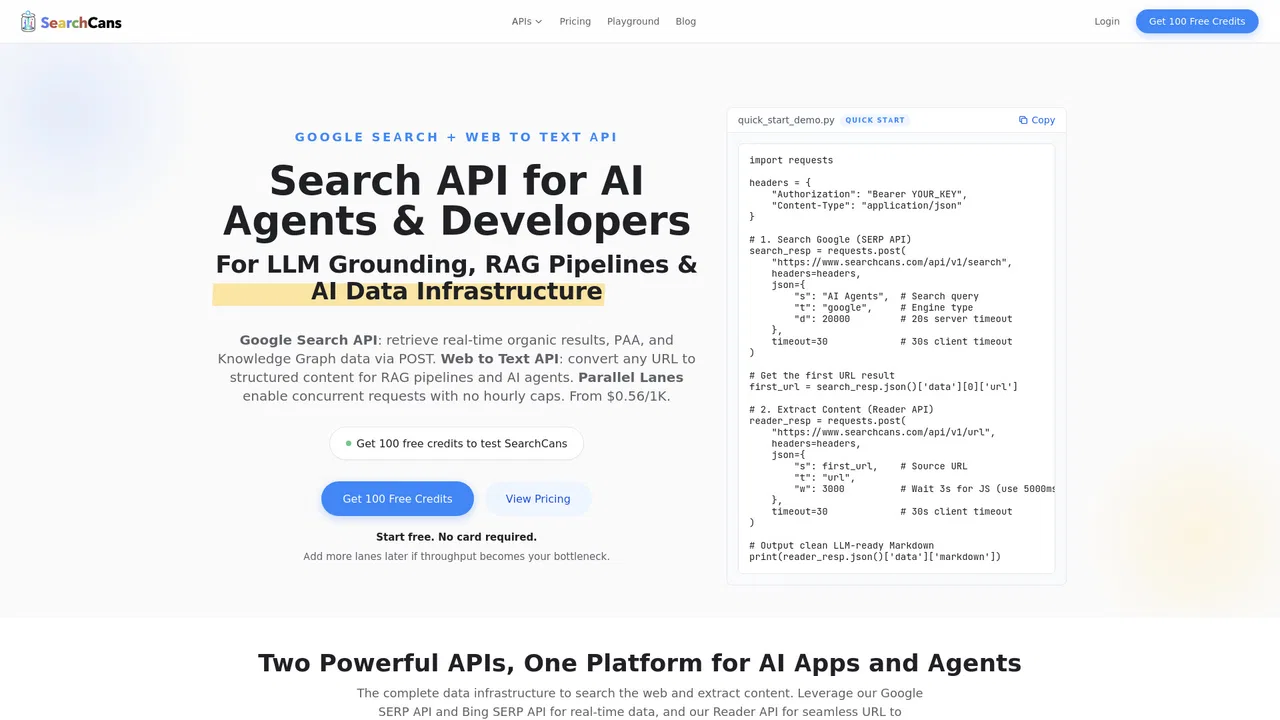
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.
月間サイト訪問数の推計
このドメインの Similarweb 推計値であり、アクティブユーザー数ではありません。観測データのある月のみ表示し、取得日と対象月を区別しています。
取得日 2026/11/11

編集部による 5 点満点の評価です。ユーザー評価の平均ではありません。 このページの各視点は、製品情報をもとに AI がまとめたものです。実際の利用者のレビューではありません。
OpenAITools.app のテレメトリ(2026-11-11 検証)によると、SearchCans(searchcans.com)は AI Web スクレイピングに分類される AI プラットフォームで、月間 4223 の訪問を生み出し、前月比のトラフィック増減は -3628(-46.2%)です。主要な地域市場はアメリカ合衆国(トラフィックシェア 58%)で、無料トライアル、有料の料金モデルで運営されています。月間ボリューム別の主な競合代替ツールには Serpex(月間 2405 訪問)、Exa(月間 106.26万訪問)、Thor Data(月間 18.2万訪問)が含まれます。
時間制限なしでSERPとスクレイピングが使える神API。
RAGパイプラインの構築にめちゃくちゃ重宝しています。
サイト検証・料金体系・同カテゴリ比較に基づき AI が多角的な論点を要約した参考視点であり、実在ユーザーの個別投稿ではありません。
Structured JSON results from Google and Bing — including Shopping, Images, News, Videos and Short Videos endpoints — for search features, monitoring and production apps.
Convert URLs, PDFs and Office documents into clean Markdown or HTML, with a configurable JavaScript wait for client-rendered pages.
Pair live SERP results with Reader extraction in one pipeline so agents, RAG systems and LLM workflows answer with current, citable context.
Scale by adding concurrent lanes rather than respecting hourly caps, and stack eligible plans to add lanes to a single account without rebuilding integrations.
Add a web screenshot endpoint and file extraction alongside search and reader, all under one key and one credit balance.
Countries and languages can be targeted per request, and the docs cover error codes, rate limits, proxy tiers and credit rules in detail.
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.
Give agents current web context by pairing live search results with extracted page content, so answers cite real sources instead of stale training data.
Build ingestion that searches for a topic, follows result URLs and converts each page into Markdown chunks ready for embedding and indexing.
Convert uploaded PDFs, Word files and web pages into clean Markdown for documentation workflows and internal knowledge bases.
Pull structured SERP JSON on a schedule to track keyword rankings and competitor visibility without maintaining scraping infrastructure.
同じ主要カテゴリの競合 AI ツールをテレメトリで並列比較
| 順位 | AI ツール | 月間訪問数 | 前月比成長率 | 直接流入の割合 | 料金 | 直接比較 |
|---|---|---|---|---|---|---|
| ● | SearchCans | 4223 | -46.2% | 直接流入 39% | 無料トライアル、有料 | 表示中 |
| 1 | Serpex | 2405 | -34.3% | 直接流入 39% | フリーミアム、無料トライアル、有料 | vs Serpex |
| 2 | Exa | 106.26万 | +16.8% | 直接流入 57% | フリーミアム、料金は要問い合わせ | vs Exa |
| 3 | Thor Data | 18.2万 | -3.5% | 直接流入 39% | 無料トライアル、有料 | vs Thor Data |
| 4 | Jina AI | 28.08万 | -16.5% | 直接流入 51% | フリーミアム、有料 | vs Jina AI |
| 5 | Dumpling AI | 1.88万 | +27.8% | 直接流入 41% | フリーミアム | vs Dumpling AI |
| 6 | TinyFish | 112.5万 | +199.7% | 直接流入 36% | フリーミアム、料金は要問い合わせ | vs TinyFish |

特化型スクレイピングと AI パイプラインのためのプロキシと Web データ API
AIエージェントのためのスクレイピング・検索・データ拡充API
XCrawl is an AI-ready web scraping API that turns websites and search engine results into structured JSON, Markdown, and screenshots for LLM pipelines, agents, and data workflows.
無料・オープンソースあらゆるサイトをAIが使えるデータに変えるWebデータAPI

Bright Data's SERP API is a real-time search engine scraping API that returns Google, Bing, DuckDuckGo, and Yandex results in JSON, HTML, or Markdown, with automatic proxy management, unblocking, and parsing, and geo-targeting at no extra cost.
無料・オープンソースセレクタではなくプロンプトで、あらゆるサイトを構造化JSONに
プロキシ・ブラウザ・アンチボット処理を内蔵したウェブスクレイピングAPI