01
73.2K/mo
Automated QA, simulation and observability for voice and chat AI agents
AI AgentEditorial score: 4.2Contact for Pricing28% direct
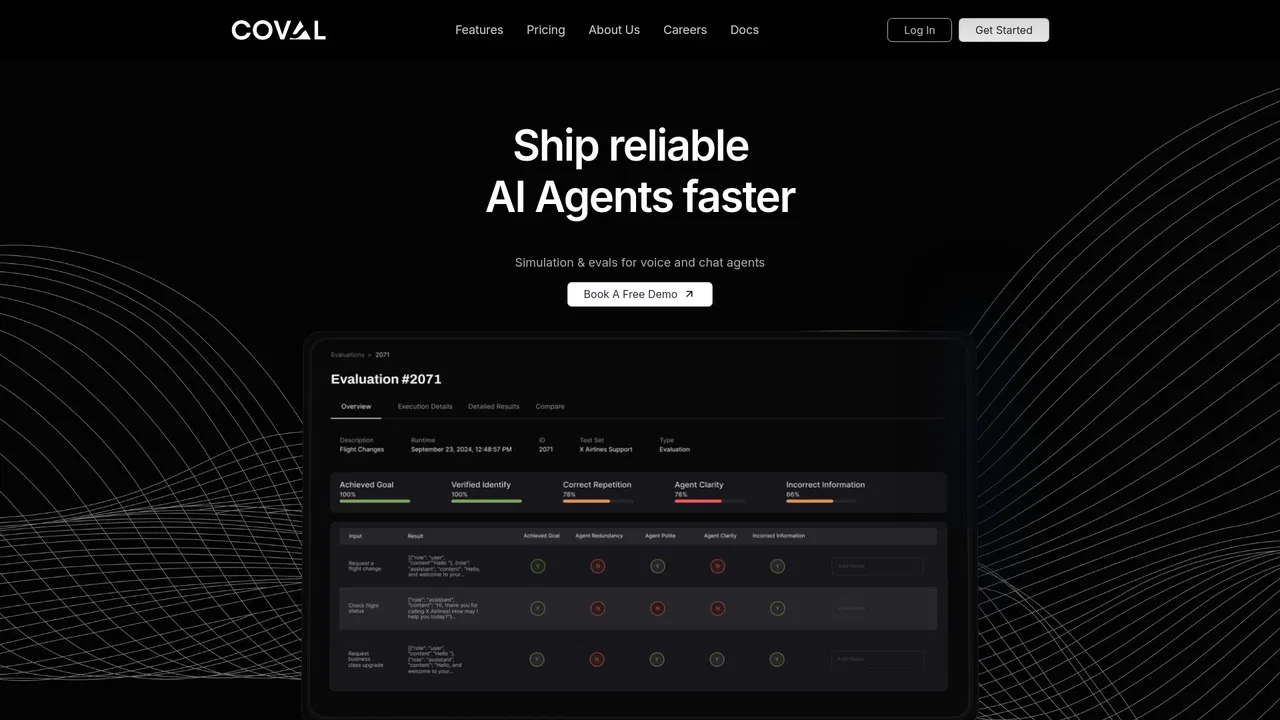
Prove your voice agents are ready — with simulation, production evals, and human QA in one loop
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Coval (coval.dev) is an AI platform indexed under AI Agent generating 161 monthly visits with a month-over-month traffic delta of -2.42K (-93.8%). Its primary geographic market is India (77% traffic share), and it operates on a Contact for Pricing pricing model. Top competing alternatives by monthly volume include Cekura (73.23K visits/mo), Roark (9.23K visits/mo), Cyara (16.7K visits/mo).
Caught edge cases in our voice agent prompts that would have wrecked live production calls.
Simulation suite is blazing fast and saved us weeks of manual QA phone dialing.
Priced for enterprise, but worth every penny if your voice bot handles real money.
Human review routing workflow is extremely well thought out.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Pressure-test agents with thousands of realistic callers, accents, interruptions, noisy audio, and hard policy traps that manual QA cannot cover.
Run evaluations on live conversations to spot where resolution, safety, or customer experience is slipping before complaints arrive.
Route the calls that matter to human reviewers and convert their judgment into sharper automated metrics for the next release.
Compare voice agent vendors and prompts side by side on the same behavioural criteria before deciding.
Access documentation, an API reference, and benchmark data to integrate evaluations into existing CI/CD and observability pipelines.
Coval is an evaluation and quality platform built specifically for voice AI agents — the automated phone assistants that handle support, banking, insurance, and booking calls. The pitch is simple and unglamorous: the riskiest call is the one you never tested, and a handful of manual QA calls will not surface the accents, interruptions, policy traps, and tool errors that decide whether an agent holds up at scale. Coval gives product, QA, operations, and compliance teams one measurement layer to answer that question with evidence rather than anecdotes.
The platform works as a three-part loop. Simulation runs thousands of realistic conversations against an agent before launch, covering personas, conversational turns, and hard policies. Observe runs evaluations against live production traffic to catch quality drift the moment prompts, models, workflows, or vendors change. Review routes the conversations that matter to human reviewers, whose judgments then sharpen the automated metrics for the following release — so every production insight becomes the next test.
Coval is aimed at teams putting voice agents in front of large customer bases. Its use cases are organised by industry — customer support, financial services, healthcare, hospitality, insurance, retail, and travel — as well as by build approach, with options for agent platforms, in-house builders shipping on LiveKit, Pipecat or custom stacks, and vendor bakeoffs. The company reports figures such as a 217% improvement in agent accuracy within seven days, 3.1 million evaluation metrics run weekly, and under 15 minutes to a first simulation via CLI, alongside documentation, an API reference, and a trust center.
Run thousands of personas, interruptions and noisy-audio scenarios against an agent before it faces real callers.
Monitor live conversations to detect where resolution, compliance, or sentiment metrics start slipping after a prompt or model change.
Ensure identity verification, escalation, and disclosure behaviours match regulatory expectations across every call.
Benchmark candidate voice agent vendors on the same behavioural criteria before signing a contract.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Coval | 161 | -93.8% | 40% direct | Contact for Pricing | Current |
| 1 | Cekura | 73.23K | -18.9% | 28% direct | Contact for Pricing | vs Cekura |
| 2 | Roark | 9.23K | +23.1% | 52% direct | Paid | vs Roark |
| 3 | Cyara | 16.7K | -48.3% | 40% direct | Contact for Pricing | vs Cyara |
| 4 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
| 5 | Relyable | 3.45K | -45.5% | 39% direct | Freemium, Paid | vs Relyable |
| 6 | Maxim AI | 121.35K | +10% | 32% direct | Contact for Pricing, Free Open Source | vs Maxim AI |
Automated QA, simulation and observability for voice and chat AI agents
Test, monitor and improve the voice AI agents you already run
Test, monitor and improve the voice AI agents you already run
Agentic CX trust platform for testing, monitoring and observing every customer journey
Agentic CX trust platform for testing, monitoring and observing every customer journey

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.

Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceEvaluate, monitor, and govern your AI applications in production

Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call
Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call

Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org
Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org

Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI
Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI

Free / Open-sourceEnterprise voice AI that resolves customer conversations
Free / Open-sourceEnterprise voice AI that resolves customer conversations

Free / Open-sourceBuild, test, and ship chat and voice AI agents for customer experience
Free / Open-sourceFind and fix problems in your AI agents before users do
Free / Open-sourceFind and fix problems in your AI agents before users do


