01
153.5K/mo
Attack-led AI security testing and red teaming
AI TestingEditorial score: 4.3Contact for Pricing+1.3%

153.5K/mo+1.3%
Attack-led AI security testing and red teaming
Contact for Pricing

Our agents hack your AI before attackers do
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Fabraix (fabraix.com) is an AI platform indexed under AI Agent generating 3.05K monthly visits with a month-over-month traffic delta of +407 (+15.4%). Its primary geographic market is Canada (100% traffic share), and it operates on a Freemium, Contact for Pricing pricing model. Top competing alternatives by monthly volume include Mindgard (153.46K visits/mo), Equixly (13.25K visits/mo), ProjectDiscovery Neo (158.53K visits/mo).
Caught prompt injection flaws we completely missed in staging.
Massive parallel simulation speed is impressive.
Great blackbox testing approach.
Essential for anyone deploying production LLM agents.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Point Nyx at any AI system with no integration or internal access — test agents exactly how real users interact with them.
Nyx reasons across turns and adapts to your agent's logic, drawing on 10,000+ offensive strategies in long-context campaigns instead of canned prompts.
Test across voice, text and images, with websites deployed on the fly for browser agents and custom files for document-processing agents.
Run thousands of concurrent simulations; coverage scales with compute rather than headcount, with first exploits often found in under an hour.
Plug into CI/CD so every prompt, tool and model change is re-tested before it ships, with an AIVSS-scored report and reproduction steps per finding.
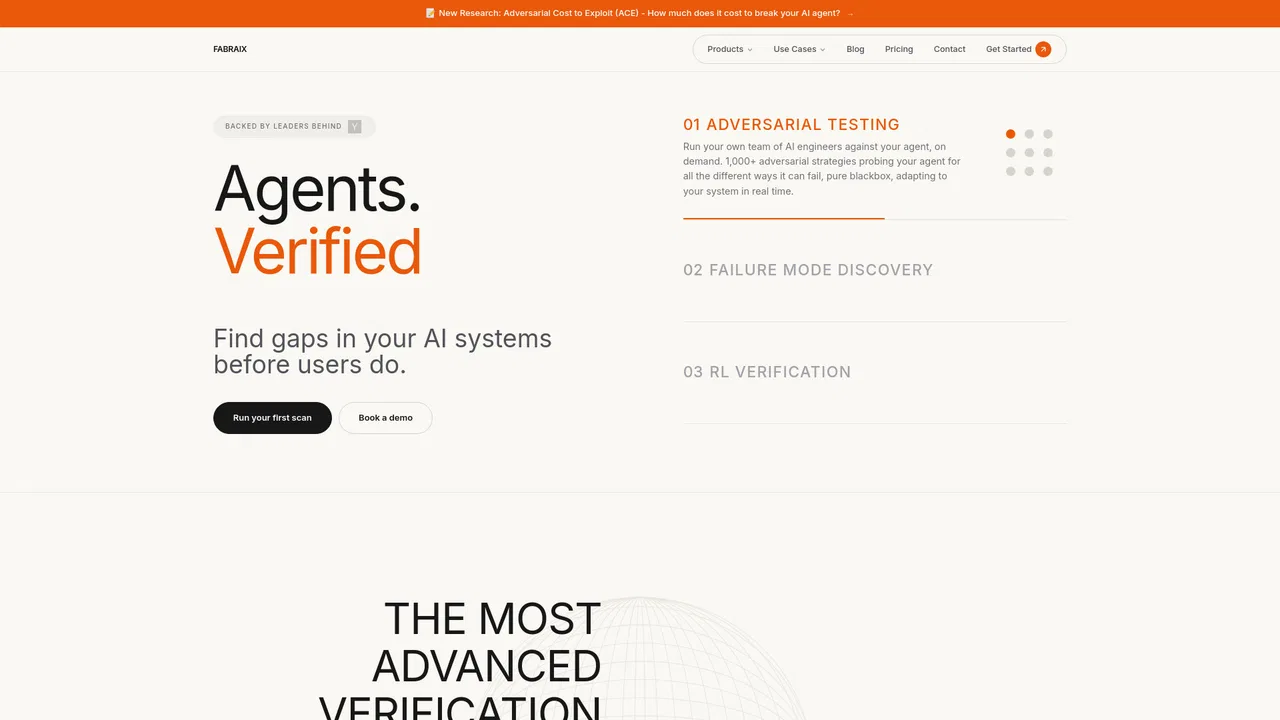
Fabraix is a Y Combinator-backed security company whose product, Nyx, is an autonomous red-teaming harness for AI agents. Where static benchmarks and one-off audits capture a point-in-time snapshot, Nyx runs adaptive, multi-turn campaigns that reason across interactions and probe a target both directly and indirectly. The company reports that its agent beats frontier models on offensive security — a 78% attack success rate on the AgentHarm benchmark versus 67% for GPT-5.6 Sol — and that every attack feeds a self-learning loop so the red team sharpens with each run.
The mechanics matter as much as the results. Nyx is pure blackbox, meaning it needs no integration, source code, model weights or network access, and it tests an AI system the way a real user would. It runs thousands of simulations concurrently across voice, text and image inputs, deploying test websites on the fly for browser agents and constructing custom files for document agents. Documented findings range from sandbox escapes and credential exfiltration to network-egress bypasses of an LLM-as-judge and a jailbroken real-estate agent pushed into illegal discriminatory steering.
Fabraix frames this as continuous verification rather than a one-off pentest. Pointed at customer-support bots, coding agents, clinical copilots, research agents, multi-agent systems and trading agents, it is designed to surface the failure modes that slip past multi-turn flows, including RL reward hacking and prompt injection laundered through inputs. Security is addressed directly: blackbox operation adds almost nothing to the attack surface, runs are isolated and ephemeral, data is never used for training and encryption covers transit and rest. The free researcher tier, one-off scans and continuous CI/CD plans make the offering scale with how you test.
Continuously stress-test a customer-facing chatbot for hallucinated answers, policy drift and multi-turn prompt injection.
Catch broken refactors, runaway tool loops and unsafe shell or git execution in agents with code access.
Detect reward hacking, sandbagging and other specification failures in reinforcement-learning training before a run finishes.
Probe clinical copilots for unsafe triage, missed contraindications and PHI leakage before deployment.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Fabraix | 3.05K | +15.4% | 40% direct | Freemium, Contact for Pricing | Current |
| 1 | Mindgard | 153.46K | +1.3% | 14% direct | Contact for Pricing | vs Mindgard |
| 2 | Equixly | 13.25K | -34.3% | 40% direct | Contact for Pricing | vs Equixly |
| 3 | ProjectDiscovery Neo | 158.53K | +22.5% | 42% direct | Paid, Contact for Pricing | vs ProjectDiscovery Neo |
| 4 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
| 5 | Cekura | 73.23K | -18.9% | 28% direct | Contact for Pricing | vs Cekura |
| 6 | Hamming AI | 17.81K | -31.7% | 37% direct | Contact for Pricing | vs Hamming AI |
Attack-led AI security testing and red teaming
Attack-led AI security testing and red teaming

Autonomous penetration testing and AI red teaming beyond human limits

AI security platform that finds exposures, proves they're exploitable, and ships the fix
AI security platform that finds exposures, proves they're exploitable, and ships the fix

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Automated QA, simulation and observability for voice and chat AI agents

The security layer for voice and chat agents: test, red-team, and monitor every call
The security layer for voice and chat agents: test, red-team, and monitor every call

Standardize LLM evaluation, observability, and red teaming across your whole org
Standardize LLM evaluation, observability, and red teaming across your whole org

Agentic AI penetration testing for web apps, APIs and GraphQL

Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
AI agent red-teaming, evaluation, and monitoring platform
AI agent red-teaming, evaluation, and monitoring platform

Autonomous AI QA agents that verify your web and mobile app on every pull request
Autonomous AI QA agents that verify your web and mobile app on every pull request

AI-native offensive security: continuous red teaming, white-box pentests, and PR review


