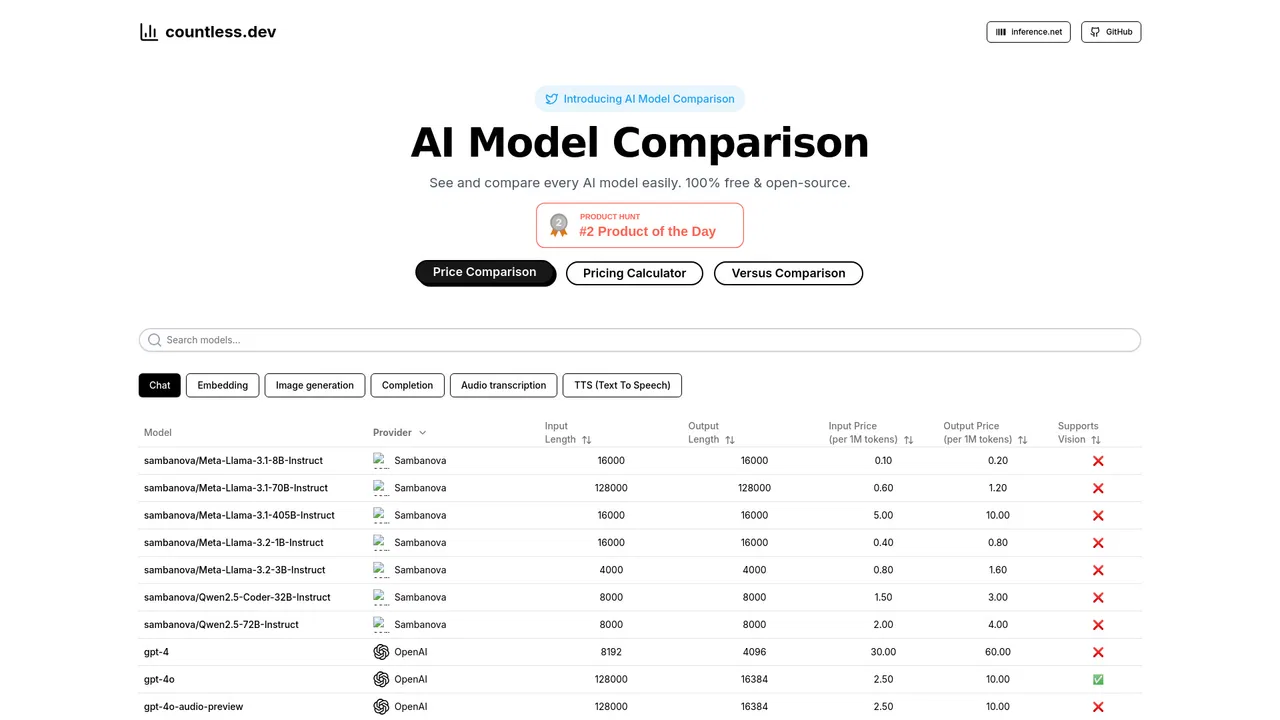
Free / Open-sourceCompare AI model prices, features and capabilities in one place

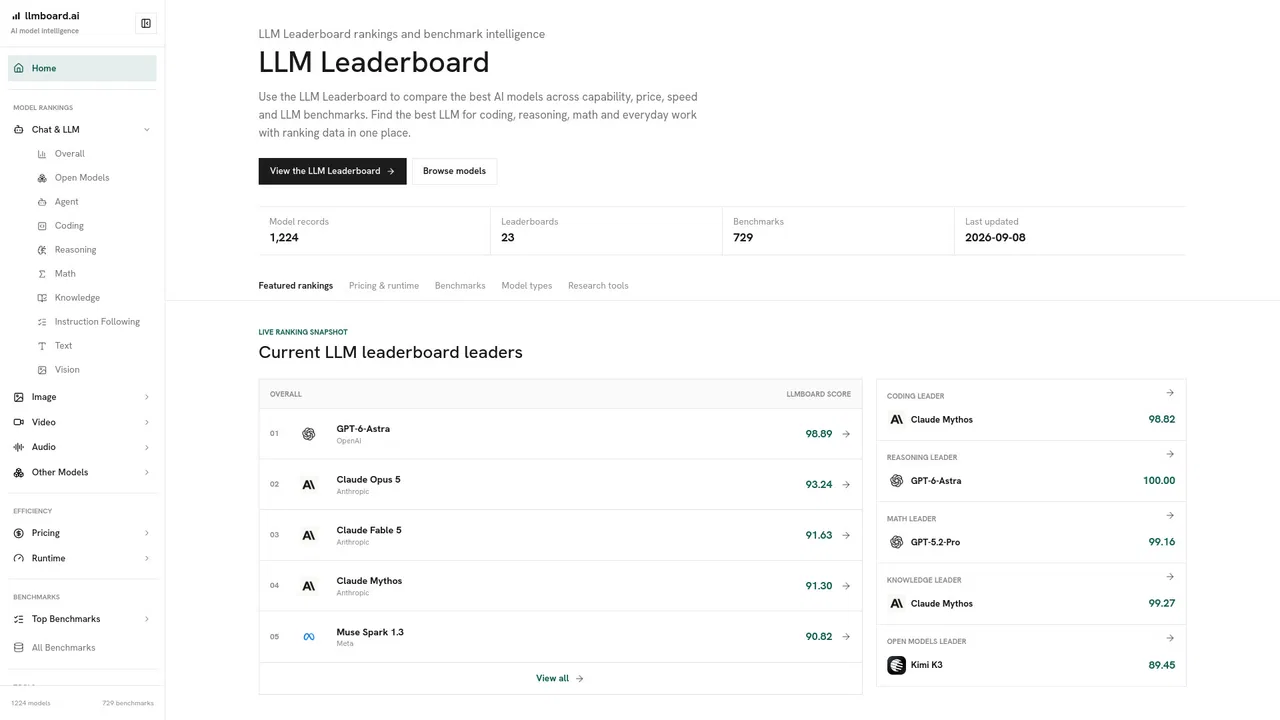
Independent LLM leaderboard for capability, price, speed and benchmarks

This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, LLMBoard.ai (llmboard.ai) is an AI platform indexed under Large Language Models (LLMs) generating 378 monthly visits with a month-over-month traffic delta of +378 (0%). Its primary geographic market is United States (100% traffic share), and it operates on a Free pricing model. Top competing alternatives by monthly volume include Countless.dev (787 visits/mo), Models.dev (200.45K visits/mo), LLM Price Check (8.26K visits/mo).
The go-to leaderboard for checking real model pricing and latency.
Clean interface and covers obscure open-source models well.
Saves so much time comparing benchmarks across MMLU and SWE-bench.
Super handy directory.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Separate rankings for overall chat, coding, reasoning, math, knowledge, instruction following, agentic tasks, vision, image, video, audio and embeddings, so you compare models on the work you actually do.
Individual evaluations such as GPQA, MMLU-Pro, AIME, SWE-Bench Verified, LiveCodeBench, MATH, HumanEval and MMMU-Pro, each with raw model order and coverage details.
Dedicated pricing views for chat tokens, image, video and audio, plus cost-versus-capability framing to identify where extra spend actually buys better output.
Output speed and latency rankings alongside provider reliability signals, covering the operational side of model choice rather than only benchmark scores.
A filterable catalogue by vendor, type, modality and price, with published scoring, coverage and model-mapping rules so rankings can be audited.
LLMBoard.ai answers a question that changes every few weeks: which model should we actually use? It maintains a continuously updated catalogue of model records and benchmark results, then presents them as leaderboards organised by task — overall chat and LLM, agentic work, coding, reasoning, math, knowledge, instruction following, plus separate tracks for vision, image generation and editing, video, text-to-speech, speech-to-text and embeddings. Each ranking is backed by named benchmarks such as GPQA, MMLU-Pro, AIME, SWE-Bench Verified, LiveCodeBench, MATH, HumanEval and MMMU-Pro.
What distinguishes it from a single-number ranking is that it deliberately separates signals. Capability scores sit apart from price, runtime latency and provider reliability, so a model that tops a benchmark is not automatically presented as the best value or the most dependable at scale. There are dedicated pricing pages for chat tokens, images, video and audio, plus speed and reliability views. A scoring and data section documents how models are mapped and scored, and each benchmark page shows raw model order and coverage so you can judge the evidence behind a position.
The site is aimed at engineering teams, product managers and researchers evaluating models for a specific workload, as well as anyone tracking how open models compare with frontier proprietary ones. It is an information and comparison resource — it does not host the models themselves, and results should be treated as a starting point for your own testing.
Filter the directory and compare coding or reasoning leaders against token price and throughput to pick a model that meets both quality and budget constraints.
Use benchmark pages, coverage notes and pricing views to justify a model choice to stakeholders instead of relying on vendor marketing claims.
Follow open-weights leaders against frontier proprietary models over time using consistent benchmark data and the published scoring method.
Pull live rankings, provider reliability and per-modality pricing to support recommendations for clients choosing between hosted APIs and open models.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | LLMBoard.ai | 378 | 0% | 33% direct | Free | Current |
| 1 | Countless.dev | 787 | -45.8% | 40% direct | Free | vs Countless.dev |
| 2 | Models.dev | 200.45K | -3.9% | 68% direct | Free | vs Models.dev |
| 3 | LLM Price Check | 8.26K | -34.7% | 39% direct | Free | vs LLM Price Check |
| 4 | Surge AI | 245.14K | +6.6% | 53% direct | Contact for Pricing | vs Surge AI |
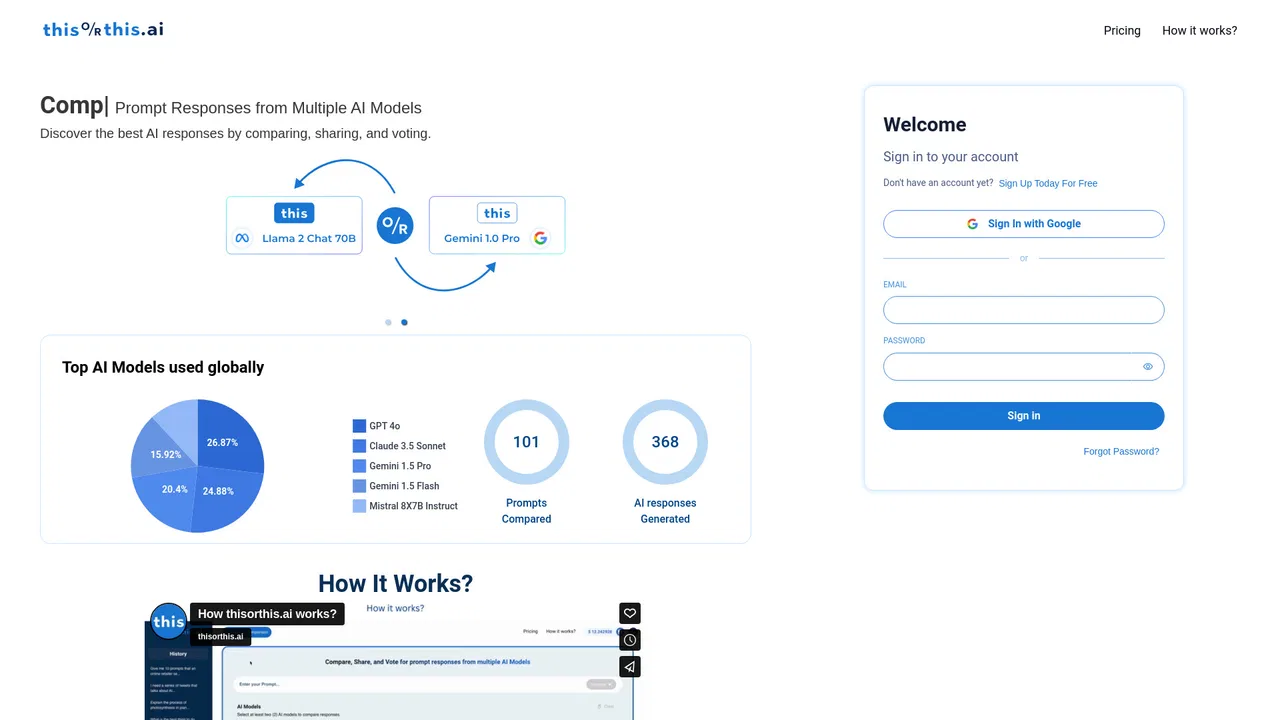
| 5 | thisorthis.ai | 2.25K | -43.7% | 39% direct | Free | vs thisorthis.ai |
| 6 | ModelFusion | 119 | -88.2% | 43% direct | Freemium | vs ModelFusion |
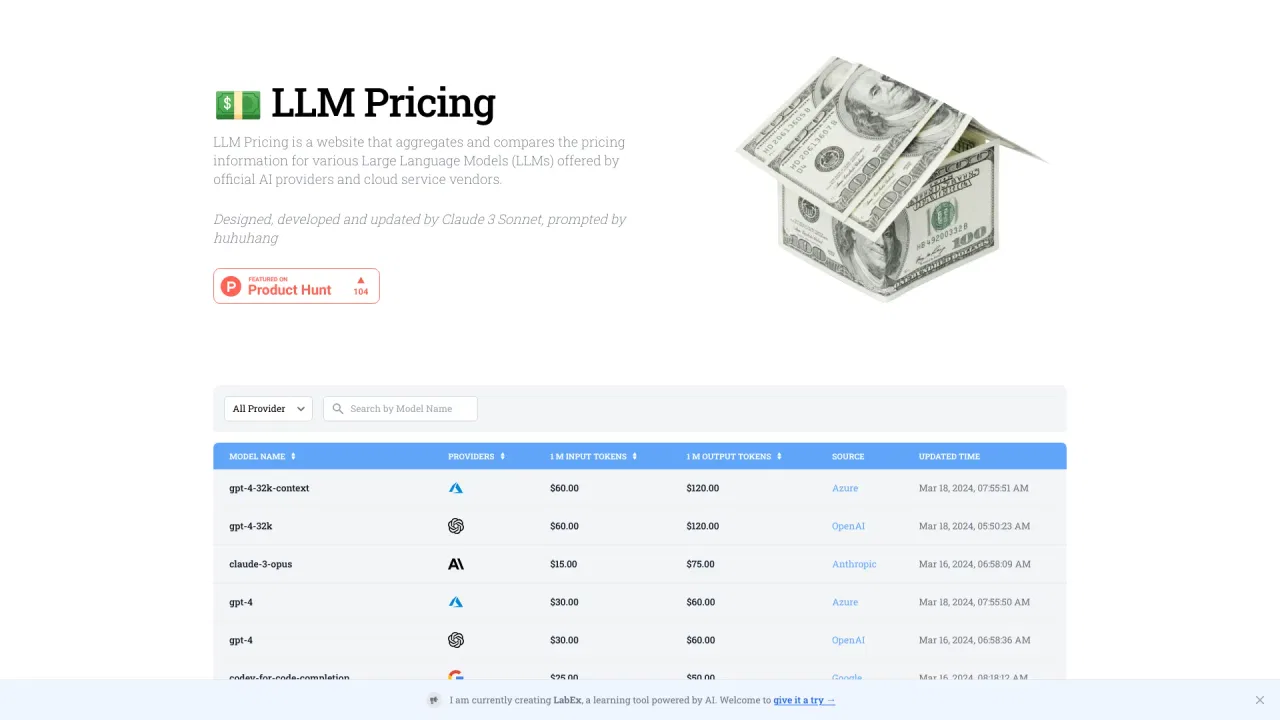
Free / Open-sourceCompare AI model prices, features and capabilities in one place

Free / Open-sourceOpen-source database of AI models, prices and capabilities

SpecialistCompare LLM API token prices across every major provider

Expert human data and evaluation for training frontier AI

Vote for the best AI each month and follow the live leaderboard

Free LLM toolkit: cost calculators, prompts and model comparison

A free archive of how every AI model answered the same 100 questions

An industry non-profit advancing the safety and security of frontier AI models
SpecialistCompare token costs across 400+ AI models

Crowdsourced arena where AI models compete and humans crown the best design output

Choose your AI stack, then prove it on real work

The top AI news and how to apply it, in five minutes a day