01
2.4K/mo
Affordable real-time search API that returns structured JSON plus page content in a single call.
AI APIEditorial score: 4.3Freemium, Free Trial, Paid39% direct
SERP and web-to-text APIs built for agents and RAG
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, SearchCans (searchcans.com) is an AI platform indexed under AI Web Scraping generating 4.22K monthly visits with a month-over-month traffic delta of -3.63K (-46.2%). Its primary geographic market is United States (58% traffic share), and it operates on a Free Trial, Paid pricing model. Top competing alternatives by monthly volume include Serpex (2.41K visits/mo), Exa (1.06M visits/mo), Thor Data (181.97K visits/mo).
Zero hourly rate limits make this a game changer for RAG pipelines.
SERP JSON is clean and the web-to-markdown reader rarely fails.
Prepaid model is way better than monthly subscription traps.
API docs could use a few more code examples.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Structured JSON results from Google and Bing — including Shopping, Images, News, Videos and Short Videos endpoints — for search features, monitoring and production apps.
Convert URLs, PDFs and Office documents into clean Markdown or HTML, with a configurable JavaScript wait for client-rendered pages.
Pair live SERP results with Reader extraction in one pipeline so agents, RAG systems and LLM workflows answer with current, citable context.
Scale by adding concurrent lanes rather than respecting hourly caps, and stack eligible plans to add lanes to a single account without rebuilding integrations.
Add a web screenshot endpoint and file extraction alongside search and reader, all under one key and one credit balance.
Countries and languages can be targeted per request, and the docs cover error codes, rate limits, proxy tiers and credit rules in detail.
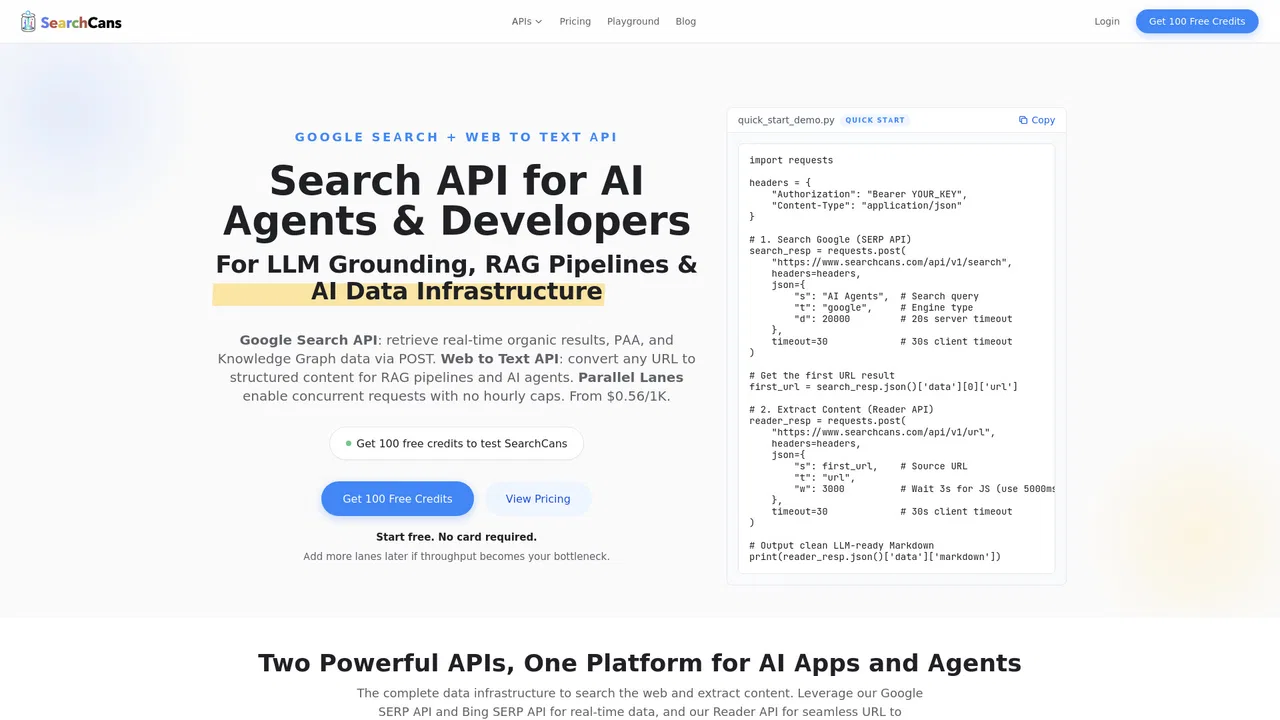
SearchCans solves a two-step problem that every agentic or RAG application hits: find the right pages, then get their content into a format an LLM can actually consume. The SERP side returns structured JSON from Google and Bing, covering standard web search plus Shopping, Images, News, Videos and Short Videos, with country and language targeting on each request. The Reader side takes a URL — or a PDF or Office document — and returns clean Markdown or HTML, with a configurable JavaScript wait so heavy single-page applications have time to render before extraction.
The API is designed to be called in sequence with a single key. A typical quick-start does a search for a query, takes the first result URL and immediately posts it to the reader endpoint, printing Markdown that is ready to feed into a model. Because both halves draw on the same credit pool, there is no separate provisioning step when you move from prototyping to production.
The commercial model is deliberately different from most SERP APIs. There are no hourly rate limits; instead throughput is governed by parallel lanes, where one lane equals one concurrent in-flight request. At a three-second average latency, a single lane corresponds to roughly 1,200 requests per hour, so a five-lane plan is about 6,000. Eligible plans can be stacked so lanes accumulate in one account, and the Ultimate tier adds a dedicated cluster node with no queue. Credits are prepaid rather than subscription-based, run from $0.56 to $0.90 per thousand after discount depending on pack size, remain valid for six months, and 100 free credits are granted at signup without a card.
Give agents current web context by pairing live search results with extracted page content, so answers cite real sources instead of stale training data.
Build ingestion that searches for a topic, follows result URLs and converts each page into Markdown chunks ready for embedding and indexing.
Convert uploaded PDFs, Word files and web pages into clean Markdown for documentation workflows and internal knowledge bases.
Pull structured SERP JSON on a schedule to track keyword rankings and competitor visibility without maintaining scraping infrastructure.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | SearchCans | 4.22K | -46.2% | 39% direct | Free Trial, Paid | Current |
| 1 | Serpex | 2.41K | -34.3% | 39% direct | Freemium, Free Trial, Paid | vs Serpex |
| 2 | Exa | 1.06M | +16.8% | 57% direct | Freemium, Contact for Pricing | vs Exa |
| 3 | Thor Data | 181.97K | -3.5% | 39% direct | Free Trial, Paid | vs Thor Data |
| 4 | Jina AI | 280.78K | -16.5% | 51% direct | Freemium, Paid | vs Jina AI |
| 5 | Dumpling AI | 18.75K | +27.8% | 41% direct | Freemium | vs Dumpling AI |
| 6 | TinyFish | 1.12M | +199.7% | 36% direct | Freemium, Contact for Pricing | vs TinyFish |
Affordable real-time search API that returns structured JSON plus page content in a single call.

Web search API and crawler built for AI agents

SpecialistProxies and web data APIs for scraping and AI pipelines
SpecialistProxies and web data APIs for scraping and AI pipelines

Search foundation built from embeddings, rerankers, and reader APIs

Web scraping, search, and enrichment APIs for AI agents
Web scraping, search, and enrichment APIs for AI agents

One API key for agent-grade web search, fetch, browsing and automation
AI-ready web scraping API for structured data
AI-ready web scraping API for structured data
Free / Open-sourceWeb data API that turns any site into clean, AI-ready content
Free / Open-sourceWeb data API that turns any site into clean, AI-ready content

One scraping API that turns any website into agent-ready JSON

Real-time search engine scraping API with structured JSON, HTML, or Markdown output
Real-time search engine scraping API with structured JSON, HTML, or Markdown output
Free / Open-sourceTurn any website into structured JSON with a prompt instead of selectors
Free / Open-sourceTurn any website into structured JSON with a prompt instead of selectors

Web scraping API with built-in proxies, browsers, and anti-bot handling
Web scraping API with built-in proxies, browsers, and anti-bot handling