載入中…

在單一受治理的工作空間中完成多模態訓練資料的整理、標註與品檢
每月造訪次數
3903
每月造訪次數
3903
月度環比成長
-2231
成長速度: -36.4%
直接流量占比
40%
直接流量占比不等於使用者留存率。
主要市場
🇺🇸美國
佔比: 57%
流量歷史
網站月造訪量估算
https://unitlab.ai
開啟線上網站 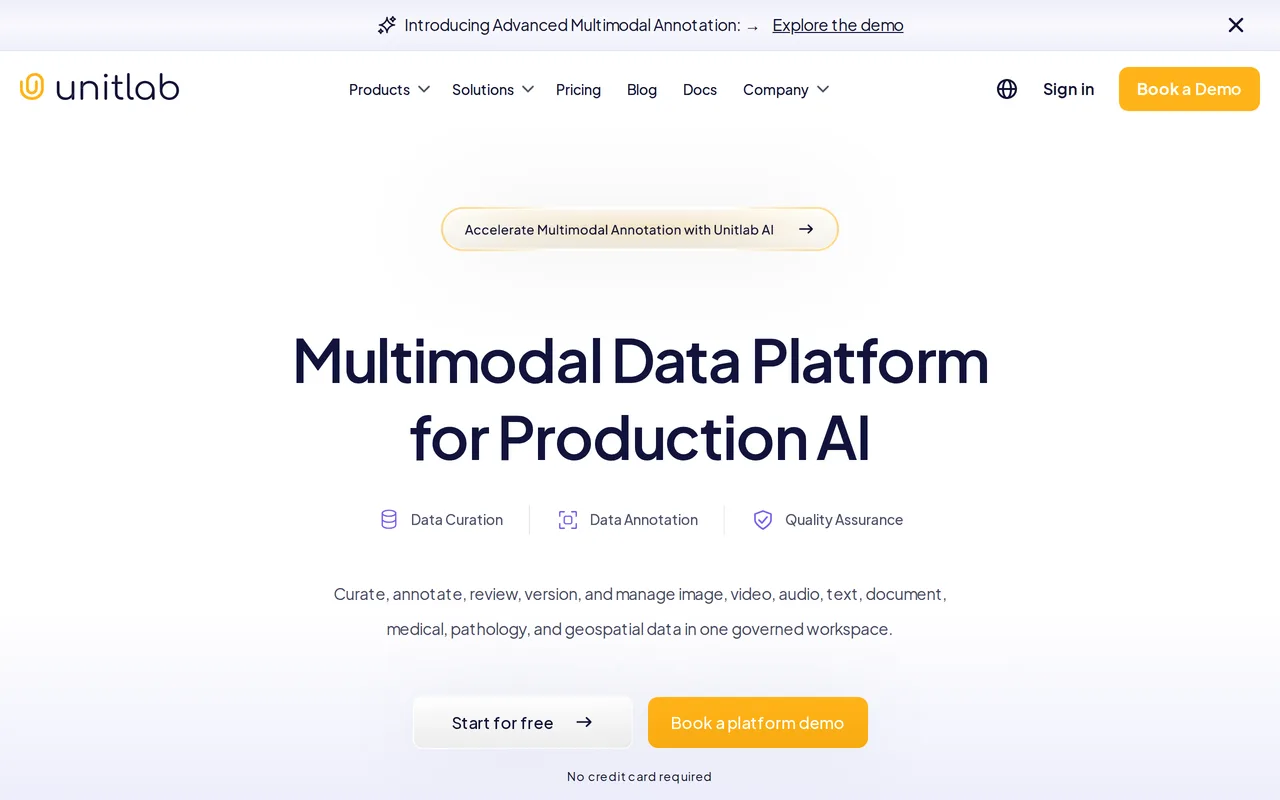
在單一受治理的工作空間中完成多模態訓練資料的整理、標註與品檢
網站月造訪量估算
資料為該網域的 Similarweb 流量估算,不是活躍使用者數。僅顯示有資料的統計月份;擷取時間與流量統計月份分別標示。
擷取於 2026年11月11日
這是編輯給出的評估,滿分 5 分,不是使用者評分的平均值。 本頁的各方觀點由 AI 根據產品資訊歸納,不是真實使用者的評價。
依據 OpenAITools.app 於 2026-11-11 查驗的觀測資料,Unitlab(unitlab.ai)是收錄於 AI 開發者工具的 AI 平台,每月產生 3903 次造訪,月流量變化量為 -2231(-36.4%)。其主要地理市場為美國(流量佔比 57%),並採用免費增值、需聯絡報價定價模式。依每月流量計算的主要競爭替代方案包括 Encord(每月 24.42萬次造訪),SuperAnnotate(每月 38.6萬次造訪),Labelbox(每月 76.28萬次造訪)。
資料版本控制跟多模態標註真是有夠強,省超多時間。
介面流暢,自動標註準確率也算水準之上。
以下短評基於實時網頁探查、定價機制與同類基準由 AI 綜合生成,用於呈現不同情境下的常見亮點與槽點,非實名真實用戶留言。
在同一個受治理的工作空間中標註影像、影片、音訊、文字、文件、醫學影像、病理、地理空間、感測器與表格式資料,不必拼湊多個獨立工具。
把自有模型接入標註流程進行預標註、分割與物件追蹤,並可將多個模型階段與人工複核結合,審核通過前每一筆預測都能編輯或驗證。
Consensus、Quality Gate 與專家複核三階段以對標註員隱藏的正解驗證標籤,確保訓練資料可靠——Unitlab 聲稱品檢準確率可達 99% 以上。
隨資料演進建立資料集版本,指派任務、追蹤變更,並讓標註歷史與標籤血統在整個 AI 生命週期中可稽核。
以語意理解搜尋大型資料集,並透過嵌入視圖發現離群值、定位標註問題,在進入訓練前修正。
共享本體、屬性、存取控制與協作工具,讓標註員、審核員與工程師基於同一套受治理的定義協同工作。
Unitlab 是為訓練正式上線 AI 的團隊打造的資料平台。它不把標註視為獨立任務,而是打通通常分散在不同工具中的三個階段:資料整理(找出並準備相關樣本)、含品質保證的標註(可靠地貼標),以及資料集管理(對結果進行版本化與治理)。官方說明的效益包括標註速度提升約 15 倍、資料營運時間減少約 60%,以及訓練資料成本最多降低 5 倍。
平台的差異點在於多模態涵蓋能力。它支援 12 種以上模態與 120 多種格式,從常見的影像與影片任務(物件偵測、分割、關鍵點、追蹤、3D 立方體、LiDAR),一路延伸到 DICOM 與體積醫學影像、全切片病理、衛星與航拍地理空間影像、PDF 與 OCR 文件欄位、HTML 文字片段、帶講者標籤的音訊、感測器時間序列與表格式資料。彼此關聯的資料還能在共享脈絡中標註,例如對齊影片影格與音訊時間軸,或把影像與擷取出的文字和中繼資料串連起來。
品質控制被視為核心功能。Consensus 會把獨立標註結果與可設定的一致性門檻比較,Quality Gate 用對標註員隱藏的正解檢查提交內容,專家複核則處理歧異。Unitlab 也支援自帶模型進行預標註、跨資料集的語意搜尋,以及用來找出離群值與標註問題的嵌入視圖。它被應用於機器人、醫療、遙測、零售、物流、農業、身分識別與金融科技等領域,提供免費起步層級,企業方案則依資料量與部署需求擴充。
在影像與影片上標註偵測、分割、關鍵點與追蹤資料,並在標籤進入訓練流程前通過一致性檢查。
標註 DICOM 與體積資料、全切片病理與臨床文件,配合受治理的品檢流程與完整標籤血統,滿足合規審查要求。
在共享標註流程中整合 LiDAR、同步相機影格、感測器時間序列與文字中繼資料,服務自駕與機器人系統。
對衛星與航拍影像進行土地利用、作物健康與變化偵測標註,並在新影像到來時對資料集進行版本化。
利用語意搜尋與嵌入視圖找出錯誤標註或離群樣本,在重新訓練前清理既有資料集。
同一分類下同類 AI 工具的流量並排比較
| 排名 | AI 工具 | 每月造訪次數 | 月增幅 | 直接流量占比 | 價格 | 正面對決 |
|---|---|---|---|---|---|---|
| ● | Unitlab | 3903 | -36.4% | 40% 直接流量 | 免費增值、需聯絡報價 | 目前產品 |
| 1 | Encord | 24.42萬 | +9.4% | 43% 直接流量 | 需聯絡報價 | 對比 Encord |
| 2 | SuperAnnotate | 38.6萬 | +37.4% | 64% 直接流量 | 免費試用、需聯絡報價 | 對比 SuperAnnotate |
| 3 | Labelbox | 76.28萬 | -22.8% | 49% 直接流量 | 需聯絡報價 | 對比 Labelbox |
| 4 | Label Studio | 13.72萬 | -16.1% | 34% 直接流量 | 需聯絡報價、免費 | 對比 Label Studio |
| 5 | Voxel51 | 11.77萬 | -8.2% | 29% 直接流量 | 需聯絡報價 | 對比 Voxel51 |
| 6 | Ultralytics | 79.34萬 | +8.7% | 30% 直接流量 | 免費增值 | 對比 Ultralytics |

SuperAnnotate is an AI data platform that combines a collaborative multimodal annotation editor, an expert data-operations team, and the orchestration layer needed to move curated datasets into training, evaluation, and production pipelines. It is aimed at teams building computer vision, NLP, audio, and generative AI systems who need reliable, high-quality ground truth at scale.
SuperAnnotate is an AI data platform that combines a collaborative multimodal annotation editor, an expert data-operations team, and the orchestration layer needed to move curated datasets into training, evaluation, and production pipelines. It is aimed at teams building computer vision, NLP, audio, and generative AI systems who need reliable, high-quality ground truth at scale.

免費 / 開源Label Studio is an open-source data labeling and AI evaluation platform from HumanSignal. It handles images, video, audio, text, documents, time series and agent traces in one flexible workspace, and connects to your ML pipeline through an API, Python SDK and webhooks.
免費 / 開源Label Studio is an open-source data labeling and AI evaluation platform from HumanSignal. It handles images, video, audio, text, documents, time series and agent traces in one flexible workspace, and connects to your ML pipeline through an API, Python SDK and webhooks.

免費 / 開源Voxel51 is the data platform for physical AI, built on the open-source FiftyOne library. It helps computer vision and robotics teams search, visualize, curate, annotate, and evaluate multimodal datasets — images, video, 3D scenes, and sensor streams — so they can find where models fail and fix the data behind them.
免費 / 開源Voxel51 is the data platform for physical AI, built on the open-source FiftyOne library. It helps computer vision and robotics teams search, visualize, curate, annotate, and evaluate multimodal datasets — images, video, 3D scenes, and sensor streams — so they can find where models fail and fix the data behind them.
瀏覽器端 AI 資料標註,一次提示即可標完整批影像